Beyond “Hours Saved”: Yannick Hänggi on the Real Business Case for Rewiring the SDLC with Agentic AI
Q1. Many organizations still judge AI coding and delivery tools by output: code generated, tickets closed, hours saved. A recent survey of 300 engineering leaders by Undo (*) found that 79% say release cycles are no faster than before, even though writing code is easier. In the programs you have worked on across the PDLC and SDLC, which measures proved useful for value creation, and which ones misled? If “hours saved” is not the answer, what is the right unit of value: lead time, defect escape, cost per delivered change, time to market, or something else?
Measuring AI transformation by lines of code generated, tickets closed, or self-reported “hours saved” is a classic local-optimisation trap. As Lamarre, Smaje, and Zemmel (2023) argue in Rewired, sustainable digital and AI outperformance never comes from bolting isolated point tools onto legacy tasks but requires rewiring end-to-end business domains.
Across both software providers and regulated financial institutions, we consistently observe that accelerating code generation simply shifts the bottleneck to the right along the value chain, accumulating in code review, integration testing, security sign-off, and release management. The harder an organisation pushes local coding speed, the more acute that downstream shift becomes. In fact, the recent survey by Undo (2026) highlights precisely why 79% of engineering leaders see no faster release cycles: when developers generate code faster than teams can comprehend it, “comprehension debt” accumulates. As a consequence, Undo (2026) reports 81% of surveyed organisations are suffering production incidents from AI-generated code and 91% experiencing serious defects or test escapes. Ultimately, optimising for coding speed alone inflates activity at the expense of systemic stability.
To measure genuine value creation, organisations need a two-tiered measurement framework:
- Systemic flow and stability (DORA Metrics): For software providers and IT functions, the DORA metrics remain the industry standard for benchmarking against high-performing peers because they force leaders to balance velocity (deployment frequency, lead time for changes, and time to feature implementation) against quality and stability (change failure rate and failed deployment recovery time) (DORA, 2024; Forsgren, Humble, & Kim, 2018). If AI reduces coding time by 40% but your Change Failure Rate spikes because “almost-right” agentic code slips into production, net value is negative.
- The operational unit of value: In our experience, the most reliable unit of value in the SDLC is lead time andcost per validated, defect-free production change, rather than “hours saved”. At the enterprise product level, practice proves time to market for validated customer capabilities to be the most reliable unit of value.
Outside of core software engineering, introducing AI triggers a foundational and often long-overdue discussion within business teams to define what actually drives value and what distinguishes “good” output from “bad” output. Ultimately, AI implementation cannot be treated as a one-off tool deployment. Step zero must be end-to-end process reimagination, followed by continuous monitoring and iterative expansion along the workflow reconstruction journey.
References (Q1)
- DORA. (2024). DORA’s software delivery metrics: The four keys. Google Cloud. https://dora.dev/guides/dora-metrics/
- Forsgren, N., Humble, J., & Kim, G. (2018). Accelerate: The science of lean software and DevOps: Building and scaling high performing technology organizations. IT Revolution Press.
- Lamarre, E., Smaje, K., & Zemmel, R. (2023). Rewired: The McKinsey guide to outcompeting in the age of digital and AI. Wiley.
- Undo. (2026). Overcoming the limitations of coding agents in complex software systems: 2026 research report. Undo Ltd. https://undo.io/research-report-2026/
Q2. Please take us through the cost side of the business case. Beyond licenses and token fees, there are costs for platform and integration work, governance and security controls, human review of agent output, training, and change management. Which of these did organizations most often underestimate? Inference costs are variable and prices may change (in the same survey, 82% of leaders feared that coding-agent costs will rise sharply). How do you build a budget and an ROI case that holds up if unit costs move?
Organisations consistently underestimate three structural cost categories that sit beneath the surface of software licences and token fees:
- Architecture-wide security and governance controls: Building security and access controls into the underlying architecture, tools, and platforms is the most frequently underestimated implementation cost. Giving AI agents safe access to operational data requires fine-grained runtime governance. If organisations do not integrate security as a foundational pillar from day one, retrofitting controls becomes a major bottleneck that halts production rollouts.
- Adoption, training, and change management: Enterprises routinely channel nearly all their resources into pushing tools into production, overlooking the reality that value is only generated through effective, everyday usage. In Rewired, Lamarre et al. (2023) advise that for every dollar spent on developing or licensing digital technology, organisations should budget another dollar for workflow redesign, capability building, and change management. In practice, this proves to be true across every major AI transformation we have observed.
- Human verification overhead: When coding or knowledge agents generate high volumes of plausible output, the cognitive load on senior specialists to review, verify, and debug that output increases substantially (Undo, 2026).
While those three structural costs determine whether an AI programme can launch safely, long-term ROI depends equally on mastering the variable operating expenditure of the system specifically, inference and token consumption. With 82% of engineering leaders concerned that coding-agent costs will rise sharply as multi-step agentic reasoning expands (Undo, 2026), a static IT budget is no longer fit for purpose. Moving from predictable implementation costs to volatile run-rate costs requires shifting from passive licence budgeting to active architectural cost control.
To keep inference costs under control and safeguard a positive ROI, organisations must centrally steer inference usage. You cannot burden all employees with the task of tracking how many tokens different models consume or deciding which model to select for each sub-task. Instead, a central AI Gateway must incorporate intelligent model routing, overseen by a dedicated central team of experts.
This central function protects the business case through four mechanisms:
- Automated model routing: A central LLM-based router analyses incoming prompts and context at the gateway and directs each request to the model that achieves the required output quality at the lowest unit cost.
- Continuous model portfolio grooming: The central expert team continuously evaluates new models entering the market, retires outdated or cost-inefficient models, and ensures strict regulatory and enterprise compliance across all hosted and external models.
- Centralized context engineering: Because bloated context windows drive runaway token consumption, this team manages centralised context optimisation, feeding these best practices directly back into employee training programmes so users learn to work effectively and efficiently with AI.
- Value-capped unit economics and circuit breakers: Financially, the business case should establish a hard ceiling on allowable inference spend per completed workflow (e.g., cost per resolved ticket or validated pull request) to protect contribution margins if unit prices shift. Operationally, these hard budget caps also act as an essential safety mechanism serving as automated circuit breakers that halt rogue or looping agents before they can trigger runaway token expenditure.
References (Q2)
- Lamarre, E., Smaje, K., & Zemmel, R. (2023). Rewired: The McKinsey guide to outcompeting in the age of digital and AI. Wiley.
- Undo. (2026). Overcoming the limitations of coding agents in complex software systems: 2026 research report. Undo Ltd. https://undo.io/research-report-2026/
Q3. If code becomes cheaper to produce, value and delay move elsewhere: to requirements and specifications, review, testing, release, and operations. Where did you see agentic workflows create real value along the lifecycle, and where did the benefit get absorbed by a bottleneck downstream? What does that imply for where a bank or software provider should invest first?
The most immediate, tangible value across the SDLC and PDLC is currently generated in specifications and testing.
Freeform AI coding frequently breaks down in complex enterprise systems because models lose track of architectural intent across long sessions. This can result in context rot, hallucinations, and unmaintainable technical debt. By contrast, spec-driven development frameworks, such as BMAD, GitHub Spec Kit, or OpenSpec, integrate seamlessly into the SDLC via agentic frameworks that mirror established agile workflows. These frameworks decouple development into isolated, low-context phases (e.g. defining requirements, planning architecture, and executing atomic tasks) which substantially reduces cognitive load on developers and enables them to orchestrate multiple workstreams in parallel. Concretely, markdown-based specifications (requirements.md, design.md, tasks.md, and project constitutions) are version-controlled alongside the source code, acting as executable “operating system code” for the AI team and ensuring consistent, structured artefacts across the entire lifecycle.
In testing, parallelising multiple agents unlocks massive efficiency gains by executing comprehensive test suites simultaneously in a structured way. Provided prompting and artefact schemas are engineered with rigour, agentic testing improves both consistency and auditability, giving compliance teams and regulators end-to-end traceability.
However, unless an organisation can agentify every stage of the lifecycle simultaneously, accelerating specifications, code generation, and testing inevitably shifts the bottleneck downstream into code reviews, release cycles, and production operations. Sustaining value after go-live requires a structural shift in the operating model: data scientists, engineers, and compliance experts must continue collaborating closely to adapt the agent network to new scenarios and refine human-agent handoffs. A portion of the initial productivity dividend must be reinvested into monitoring and managing the system. This is especially important, when processes are nearshored or offshored and operational quality control sits far from central compliance specialists.
To mobilise the wider enterprise toward agentic AI, the SDLC has proven to be the optimal starting domain. Because every digital transformation ultimately runs through IT, enhancing and debottlenecking IT first prevents technology delivery from becoming the enterprise choke point. Moreover, the SDLC is where the technical talent resides to build the foundational platforms required to scale agentic workflows rapidly across the rest of the organisation, such as the agentic AI factory, LLM platform, central AI gateway, governed data flows, and security layer.
Q4. You work in banking, where the business case must include risk, governance, and security architecture, and not only benefits. How do you treat the cost of control in a business case: as a deduction from ROI, or as the condition that makes the benefits possible? There is also a question of who captures the gains when delivery gets cheaper. In a chain of software provider, bank, and end customer, does it go to the provider’s margin, to lower prices, or to faster time to market, and does that change how work is priced and contracted?
In banking, risk, governance, and security standards are non-negotiable. Consequently, the cost of control is not a deduction from ROI but rather the foundational condition that makes deploying AI and capturing any ROI possible.
In practice, banking business cases follow a two-phase trajectory:
- Initial deployment (quality and risk dividend): Unit costs often rise initially because new agentic workflows require extensive human-in-the-loop (HITL) verification gates to guarantee output quality and regulatory compliance. However, automating repetitive groundwork allows human specialists to focus on complex judgement calls, significantly raising overall output quality. This constitutes a risk-reduction benefit that must be explicitly accounted for in ROI calculations.
- Mature scaling (margin dividend): Once workflows operate reliably within proven guardrails, routine HITL gates can be progressively reduced in favour of exception-based oversight, allowing efficiency gains to flow directly into margin expansion.
Regarding the capturing of the economic surplus across the value chain, the gains distribute dynamically depending on which stages of the workflow are AI-optimised. Initially, most incumbent banks prioritise faster time to market, using agentic delivery to close the digital offering and client-proximity gap versus digitally native challengers. In the long term, margin capture diverges by strategy: relationship-focused banks can reinvest efficiencies to increase the quality, breadth, and depth of their offerings at stable price points, whereas scale-focused players can pass the savings on through lower fees for standardised products.
Crucially, cheaper and faster delivery is reshaping how software and IT services are priced and contracted. Traditional time-and-materials- or FTE-based billing models penalise software providers for agentic efficiency. As a result, contracting between banks and technology partners is shifting toward fixed-price capability delivery and outcome-based pricing, where providers protect or expand their margins by delivering validated, defect-free software faster rather than billing for raw developer hours.
Q5. Organizational impact is often the hardest part to measure. You helped lead a rollout of an enterprise chat and retrieval platform to more than 300 consultants, with about 30% less time spent on search. What happened to the time saved? How do you check that a measured gain turns into value and does not just disappear into more work? Beyond time, what changes did you see in roles, in skills, and in how junior people learn when agents do the routine work?
Without deliberate management, a 30% reduction in search time easily falls victim to Parkinson’s Law: the tendency for work to expand so as to fill the time available for its completion (Parkinson, 1955). To ensure that measured time savings converted into real business value across those 300+ consultants, we tracked output quality, knowledge reuse, and team leverage rather than self-reported hours saved:
- Deeper analysis within constant delivery windows: The hours saved on information retrieval were systematically reinvested into deeper quantitative analysis and higher-quality client deliverables. More client value was created within the exact same delivery window.
- Cultural shift in knowledge liquidity: By making previously fragmented institutional knowledge centrally accessible, the platform strengthened cross-practice interconnectivity, fostering a stronger culture of knowledge exchange and mutual support across the firm.
- Rebalancing the talent pyramid and accelerating junior apprenticeship: While demand for large cohorts of junior consultants solely to perform manual groundwork diminished, the developmental experience for the juniors who joined improved markedly. Because project managers and partners spent less time supervising basic data gathering, they had greater bandwidth to coach and onboard junior colleagues properly. Moreover, with instant access to the firm’s collective knowledge and AI acting as an everyday sparring partner, junior consultants were integrated into higher-complexity, higher-value tasks far earlier in their careers.
References (Q5)
- Parkinson, C. N. (1955, November 19). Parkinson’s law. The Economist, 177(5856), 635–637.
Q6. You were a professional athlete before consulting. In sport, performance is tracked by many numbers, yet athletes also learn that some numbers mislead and that discipline matters more than any single metric. Did that background shape how you think about measuring AI transformation? What is one lesson from sport that you rely on when a project is not going well?
Definitely. My years playing professional ice hockey coincided with the rise of data- and analytics-driven performance optimisation. Much like enterprise AI today, that shift divided teams and front offices into sceptics and enthusiastic adopters. Because I was highly interested in the space, I worked closely with leading sports-tech firms and start-ups, applying those technologies to my own daily training and on-ice performance. That experience taught me a lesson that applies directly to banking and software engineering: data and AI are extraordinary multipliers for workflow optimisation and insight generation, but the human element remains indispensable for supplying the tacit context that algorithms cannot capture.
To optimise human-AI collaboration for maximum output quality, you cannot simply layer AI onto legacy habits (Lamarre et al., 2023). You must iteratively define the scope of each workflow, decompose processes into explicit sub-steps, and establish unambiguous criteria for completion. The redesign has to start from a first-principles question: how should AI and humans best divide the work?
- Designing for AI strengths: Unburdened by legacy norms or fatigue, AI does not need to take process shortcuts, which dramatically improves analytical completeness.
- Designing for human judgement: Every decision framework must capture more than written policies; it must incorporate the situational context and nuance that determine how an ambiguous case should be read. That judgement can only be supplied by domain experts. Capturing the full opportunity of AI requires placing the human in the loop at those exact decision inflection points, while ensuring autonomous agent steps produce outputs reliable enough for humans to trust.
When an AI project is not going well, I rely on a core discipline from professional ice hockey: take the emotion out of the dressing room, stop staring at the scoreboard, and review the video to isolate the system breakdown. In ice hockey, when a team is conceding goals, panicking about the scoreline or singling out individuals only compounds the mistakes. Instead, you analyse where the gameplan broke down. Whether in defensive-zone coverage or transition – focus on fixing the system design and train the players on the ice so they execute it properly next time. When an enterprise AI programme stalls, I apply the exact same discipline: we strip away the hype and finger-pointing, inspect the workflow telemetry to isolate where the human-agent collaboration system broke down, adjust the architecture and process handoffs, and train the team to execute the refined workflow with confidence.
References (Q6)
- Lamarre, E., Smaje, K., & Zemmel, R. (2023). Rewired: The McKinsey guide to outcompeting in the age of digital and AI. Wiley.
Qx. Anything else you wish to add?
If there is one overarching takeaway for banking and software executives, it is to stop treating agentic AI as a plug-and-play productivity tool and start treating it as an end-to-end operating model transformation. The organisations that turn AI into a durable competitive advantage are not those generating the most lines of code or chasing isolated “hours saved”. Instead, they make end-to-end process reimagination step zero, build their foundational platforms and security controls in the SDLC from the outset, steer variable inference economics centrally through an intelligent AI gateway, and invest just as heavily in change management and human-agent collaboration as they do in the underlying models. In regulated industries especially, speed without architectural control is a liability. But when rigorous governance, spec-driven engineering, and human judgement are designed into the system from day one, agentic AI becomes a true multiplier for both velocity and quality.
……………………………………………………..
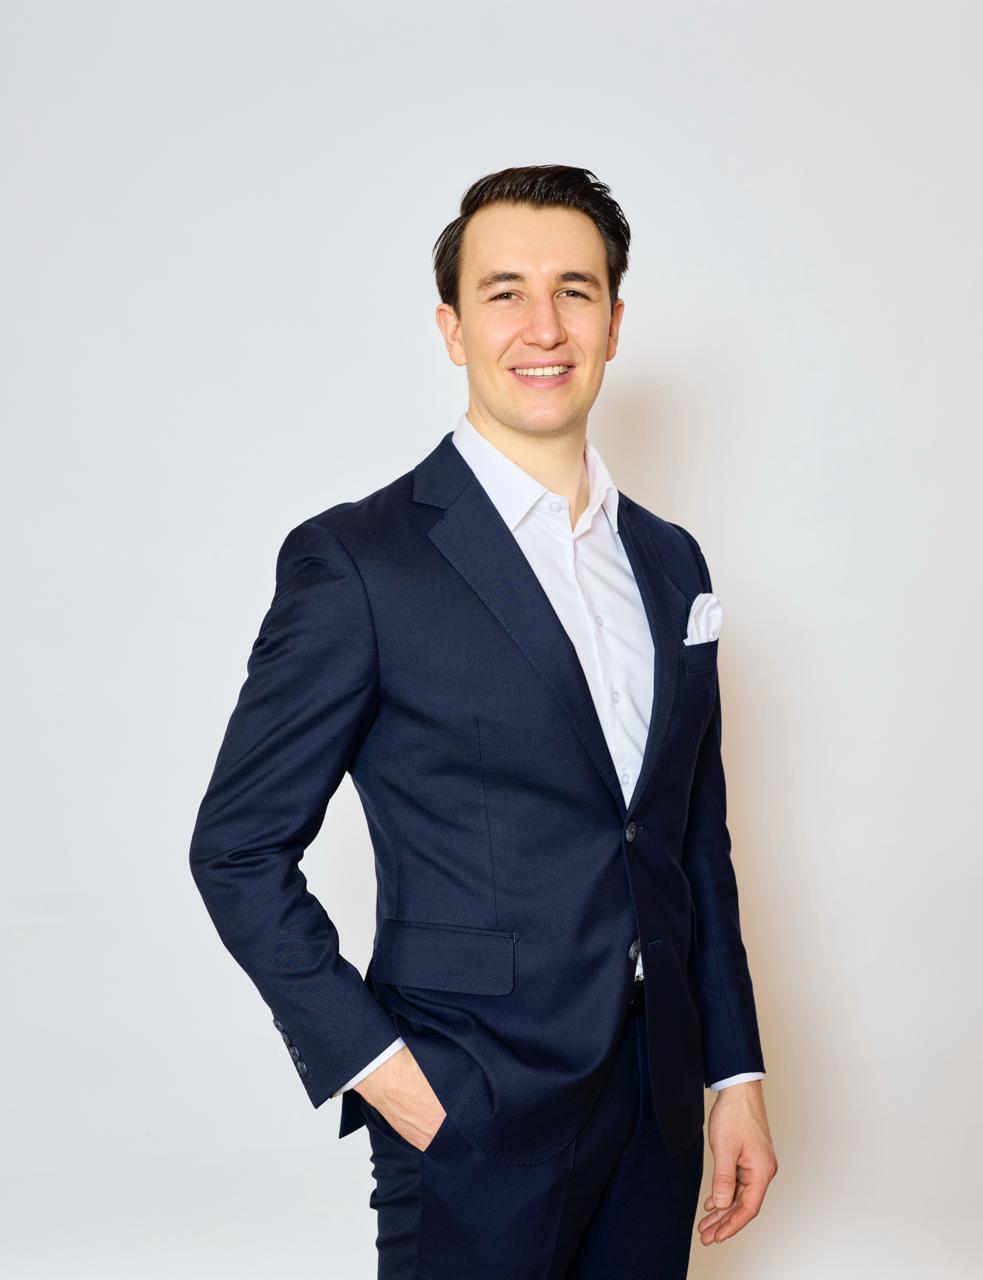
Yannick Hänggi is a Manager at Horn & Company in Zurich, where he leads banking and AI-driven operating model transformations. His work focuses on enterprise-wide agentic AI strategy across the SDLC (software development lifecycle) and PDLC (product development lifecycle), target architecture, AI governance, and scaling generative AI and retrieval platforms across regulated institutions. Prior to entering strategy consulting, he competed for seven years as a professional ice hockey player in the top-tier Swiss and German leagues. He holds an M.A. in Business Innovation and a B.A. in Business Administration (with a focus in Computer Science) from the University of St. Gallen (HSG), as well as a CAS in Machine Learning in Finance & Insurance from ETH Zurich.