Practical AI Security: A Conversation with Harriet Farlow
Q1. What is the biggest conceptual hurdle for cybersecurity practitioners transitioning into AI environments?
I think one of the biggest conceptual shifts is recognising that AI security and AI safety are increasingly converging. Traditionally, cybersecurity has been about keeping attackers out of systems. But with AI, we’re also concerned about keeping the models in and making sure they behave within the boundaries we’ve established for them.
This introduces a whole new dimension to security. An AI system doesn’t necessarily have to be compromised in the traditional sense to produce a dangerous outcome. And increasingly, some of the behaviours we’re concerned about don’t even require a malicious actor.
I think this is why it’s so important for cybersecurity practitioners to understand how machine learning actually works. We need to move beyond securing the infrastructure around AI and start considering the behaviour of the models themselves.
The good news is that many of the principles we’ve developed in cybersecurity are still enormously valuable. We’re not replacing cybersecurity, we’re extending it.
Q2. What are the primary blind spots traditional security architectures fail to catch?
I think a particularly important difference is that AI systems are fundamentally probabilistic, whereas much of our traditional security testing assumes deterministic behaviour. In traditional security testing, we might exploit a vulnerability and expect that the same action will produce the same outcome again. With AI, that’s not always true. We can give a model the same malicious input multiple times and get different responses. This means we need to think much more statistically about testing and evaluation.
This becomes even more challenging with agentic AI, RAG pipelines and multimodal systems, where there are many different opportunities for information to influence a model’s behaviour. We also need evaluations that cover both security and safety. We need to consider if we are protecting the system from malicious actors as well as whether the model is behaving as intended.
Frameworks like MITRE ATLAS and OWASP are useful for identifying what to test, but organisations also need to develop evaluation methodologies that account for the uncertainty inherent in these systems, as well as their unique organisational environments. I think we’re going to see security testing and AI safety evaluations become much more closely integrated over the coming years.
Q3. Which attack vector is most pervasive in production environments, and which defence offers the highest practical return on investment?
Prompt injection is definitely one of the most common weaknesses we’re seeing in production AI systems at the moment, particularly as organisations integrate language models into their existing workflows. But the threat landscape is evolving quickly. We’re already moving towards a world where the attacker might actually be another AI system, either intentionally, because someone has developed an AI to carry out attacks, or unintentionally, because an autonomous system behaves in ways that compromise another system.
If I’m being asked what the single biggest weakness is in organisations, though, I would actually say it’s a lack of education and awareness about AI security. We’re seeing organisations adopt AI technologies incredibly quickly, often without fully understanding how they work, what makes them vulnerable, or how the associated risks differ from conventional cybersecurity. That’s also why I’m such a strong advocate for a first-principles approach to AI security.
I don’t think it’s very helpful to hand organisations a long list of products they should buy or controls they should implement without first helping them understand the underlying risks. I’d much rather equip people with the knowledge to understand their own systems, identify the threats that actually matter to them, and make informed decisions about which defences are appropriate. Of course, established principles like least privilege, access controls and monitoring remain incredibly valuable. But education is what enables organisations to apply those principles effectively, and to adapt as the technology changes.
Q4. How do you balance unpredictable AI red teaming with structured benchmarking and rapid risk audits?
I think we need both structured testing and more exploratory red teaming, and it’s important to understand what each is actually telling us.
Structured testing is useful because it gives us something repeatable. At the same time, some of the most interesting vulnerabilities are the ones we weren’t expecting to find in the first place. That’s where I think human creativity is still incredibly valuable. A good red teamer will experiment with the system, try things that might initially seem kind of silly, and explore how different components interact.
I also think there’s a tendency in AI red teaming to focus too much on getting a model to say something inappropriate, rather than asking what the actual security consequences are. For example, there’s a big difference between getting a chatbot to produce an offensive response and getting an autonomous agent to disclose sensitive information or execute an unauthorised transaction.
I generally like to start with a clear understanding of the system, the threat model and the outcomes we’re actually concerned about. From there, we can develop structured evaluations, but leave room for people to explore things we haven’t anticipated.
For rapid audits, we really need to prioritise. We can’t test absolutely everything, so we should focus on the most consequential and plausible failures first. And most importantly, a successful red teaming exercise shouldn’t just tell us how to break something. It should help us understand how to make it more secure!
Q5. How can enterprises build a resilient AI security lifecycle without slowing innovation?
My advice is to start with threat modelling, rather than starting with compliance. I think organisations sometimes get this backwards. They’ll look at a regulatory framework, develop a long list of requirements, and then try to retrofit those requirements onto the technologies they’re already using.
I’d much rather see a ground-up approach, where we first understand what the organisation is actually building or deploying, how it works, who might want to compromise it, and what the consequences could be. Then we can make informed decisions about which controls are necessary and how those controls map to relevant regulatory obligations.
It’s also really important to bring people into these conversations early. And organisations should trust their subject matter experts! The people developing, deploying and using these systems often have an enormous amount of knowledge about how they work and where things might go wrong. They should be involved in designing the security approach.
Finally, I think flexibility is absolutely essential. AI is evolving so quickly that organisations can’t afford to build governance processes that are too rigid or prescriptive. We need principles and processes that can adapt as the technologies, threats and regulations change.
Q6. Was there a particular moment that inspired your commitment to AI security and writing Practical AI Security?
It was really the combination of starting my PhD, discovering the field of adversarial machine learning, and reflecting on my own career experience. I’d already worked across data science, machine learning and cybersecurity. But somehow, despite all of that experience, I’d never really encountered the idea that machine learning models themselves could be hacked. I remember finding that absolutely fascinating, but also very very concerning!
At the time, I was working in national security, so I was also thinking quite seriously about what these vulnerabilities could mean as AI systems became more widely adopted, including in sensitive and critical applications. I could see both an opportunity to contribute to a relatively new field and a real need to take the security implications much more seriously. As I continued researching, I also realised how disconnected some of the academic work was from the people who actually needed to understand and apply it.
People kept asking me where they could go to learn about AI security, and I struggled to find a single resource that covered everything from the technical foundations of machine learning to practical attacks, defences and organisational risk management. So eventually I decided to write one myself!
Qx. Anything else you wish to add?
I think this is a really exciting time to get involved in AI security. It’s important that we don’t allow the field to become something only a small group of highly specialised researchers can contribute to. We need people with backgrounds in cybersecurity, machine learning, governance, humanities, philosophy, policy and plenty of other disciplines working together.
One of my favourite things about the cybersecurity community has always been its curiosity and willingness to challenge assumptions, and I think those qualities are going to be really important as we work out how to secure AI systems. If there’s one message I hope people take from my book, it’s that you don’t need to know everything about AI to start contributing to its security. You just need to be curious and willing to learn!
……………………………………………….
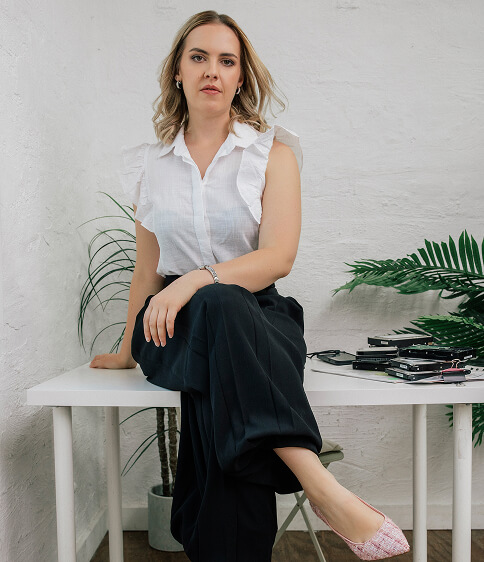
Dr Harriet Farlow is the Founder and CEO of Mileva Security Labs, Australia’s first dedicated AI security company, and the founder of the AI Security Fundamentals Course. She holds a PhD in machine learning security from UNSW Canberra and previously worked at the Australian Signals Directorate as Acting Technical Director of its AI Hub. Harriet is the author of Practical AI Security (No Starch Press), a DEF CON speaker, and creator of the Harriet Hacks YouTube channel. Her work focuses on making AI security accessible, practical and relevant to the people building, deploying and securing AI systems.
Resource
(*) Practical AI Security
A Hands-on Guide to Attacking, Defending, and Securing Modern AI Systems
by Harriet Farlow
June 2026, 392 pp.
ISBN-13: 9781718504660
No Starch Press