The AI Boardroom Strategy: Power, Regulation, and Asset Valuation with Doug Laney
Q1. Capital Allocation vs. Structural Shift
From a macroeconomic perspective, board members are currently deciding whether to treat Generative AI as a massive operational expense or a long-term capital investment. Looking back at previous IT market cycles—from the emergence of Big Data to cloud migration—is GenAI genuinely altering the structural productivity of corporations, or are boards over-capitalizing on what is essentially an expensive evolution of advanced analytics?
My read of past IT cycles, from client-server to big data to cloud, is that each was greeted as a capital revolution and then largely spent as an operational expense, with the productivity gains arriving later than the hype.
GenAI is different in kind, however, because it acts on information itself: language, judgment, and decision-making, rather than on physical processes. In my view that is a structural shift. But the returns will not accrue to whoever spends the most on models. They will accrue to whoever feeds the models something no competitor can rent, which is proprietary data. Boards that chase frontier models without investing in their own data supply chain risk over-capitalizing on rented capability. The capital asset in this cycle is not the AI. It is the data estate underneath it.
Q2. The Intangible Asset Paradox
In Infonomics, you argue that information should be measured and managed with the same rigor as traditional physical or financial assets. Yet, accounting standards like GAAP and IFRS still don’t recognize data on the balance sheet. In an era where proprietary data is the primary fuel for custom LLMs, how should a board practically quantify the financial return on its data investments to satisfy shareholders and drive enterprise value?
Accounting standards were built for an industrial economy, and information strains their assumptions. How data is treated depends on the applicable standard and on how the asset arose: acquired data can be recognized as an intangible asset, while many internally developed data costs are expensed as incurred. Whatever the accounting treatment, information has economic properties those tests were never designed for. It is non-rivalrous, so one party’s use does not deplete another’s, and it does not wear out.
Boards, however, do not need accounting recognition to manage and value information, and they should not wait for the standard setters, who are actively studying intangibles recognition but moving slowly. The infonomics discipline gives them workable valuation models today: cost-based, market-based, and economic approaches that quantify information’s contribution to specific business outcomes. The practical path is to inventory the key data assets, attach valuation models to them, tie every AI and data initiative to measurable returns on those assets, and report that in management commentary and investor materials.
Q3. Mitigating Hyperscaler Dependency
The sheer capital required for frontier AI models has created an intense concentration of power among a few tech giants. For an executive board, this introduces significant vendor lock-in and systemic risk. How should companies architect their long-term data and AI strategies to avoid becoming entirely dependent on a handful of external infrastructure monopolies?
The moat is not the model. Frontier models are commoditizing quickly, and anything you can rent, your competitor can rent. What cannot be rented is your proprietary data, so architect to own the data layer and treat everything above it as interchangeable: open formats, portable pipelines, and an abstraction layer that lets you swap models without rebuilding. Retrieve over your own data rather than fine-tuning yourself into someone else’s stack.
Boards should treat model and infrastructure concentration the way they treat supply-chain concentration: negotiate egress and exit terms up front, maintain a credible second source, and test the exit before you need it. And evaluate smaller models against your own workloads: benchmark them on your tasks, your data, and your cost and quality targets before assuming a frontier model is the only option. Dependence on a handful of hyperscalers is a choice, not a law of physics.
Q4. Governance as a Value Driver
With frameworks like the EU AI Act and evolving global compliance standards, AI regulation is shifting from a compliance checkbox to a core boardroom risk. How can executive boards strike the right balance between aggressive AI innovation and defensive data governance? Do you view strict regulation as a roadblock to corporate growth, or as a necessary framework for ethical asset protection?
Regulation is a roadblock only when governance is an afterthought bolted onto innovation. Treated as a design constraint from the start, it is a license to operate and increasingly a trust asset that customers and partners pay for. Look at what the EU AI Act actually requires of high-risk systems: risk management, technical documentation, record-keeping, human oversight, and governance and quality controls over training data. That reads like a description of the data management discipline companies should already have.
Boards already set risk appetite for financial risk. They should do the same for AI: an innovation portfolio with explicit guardrails, not a brake pedal. Data is an asset with liabilities attached. Governance is how you insure it.
Q5. The Cost of Data Underutilization
Over your decades at Gartner, Deloitte, and BARC, you have advised hundreds of executive suites. If you look at the boards that fail to extract value from their IT and data strategies, what is the single most common governance blindspot or leadership failure that modern CEOs and board members are still repeating?
The most common failure is treating data as a technology concern rather than a business asset. In most organizations, no one in the executive suite actually owns the economic performance of information. The data leader reports into IT, gets measured on infrastructure delivery, and the board reviews AI strategy without ever asking about the data supply chain underneath it. As I wrote in Infonomics, companies spend more money tracking their office furniture and PCs than their information assets, and that has barely changed.
The companion failure is measuring activity instead of value: projects delivered, dashboards built, models deployed, rather than economic outcomes. There is no inventory, no valuation, no income statement for data. Until information is managed with the same rigor as capital and labor, with someone accountable for its return, the most sophisticated AI strategy sits on an unmeasured foundation.
Q6. The View from the Witness Stand
Beyond your work in the classroom and the boardroom, you frequently serve as an expert witness in high-stakes legal disputes involving data valuation and data damages. How has looking at data through the lens of legal liability and corporate litigation changed the way you advise executives on managing data risk at the highest levels?
Litigation is where data valuation theory meets its harshest test. Courts have spent decades wrestling with whether information is property at all, and the rulings are inconsistent: some have treated lost data as nothing more than economic loss, while others have held that a document on a hard drive has the same value as a paper document in a file cabinet. I wrote about this case law in Infonomics, and its lesson for the boardroom is direct. In a courtroom you cannot gesture at data being valuable. You must demonstrate how much it is worth, to whom, and how it was harmed, using methods that withstand evidentiary scrutiny.
The practical counsel follows from that. Value your data before a dispute, not during one. Document the valuation methodology and the controls around the data the way you document financial controls, because opposing counsel will examine both. And treat data diligence like financial diligence in every acquisition. A board that cannot say what its data is worth cannot say what it has lost.
Qx. Anything else you wish to add?
Only a closing thought for your readers. The boards that win the next decade will be the ones that treat information as a balance-sheet-grade asset in practice, even where accounting rules do not yet recognize it: measure it, manage it, and monetize it. The frameworks exist. What is usually missing is the will at the top to apply them. I am always glad to continue the conversation with boards working through these questions.
…………………………………………………………….
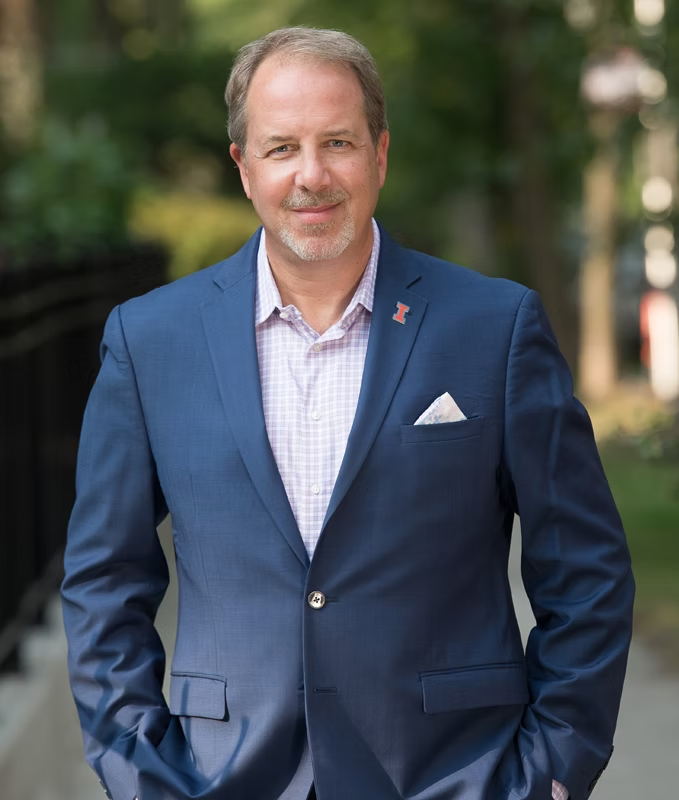
Doug Laney is a best-selling author and recognized authority on data and analytics strategy. He advises senior IT, business and data leaders on data monetization and valuation, data management and governance, external data strategies, analytics best practices, and establishing data and analytics organizations. Doug has been ranked annually as one of DataIQ’s “Top 50 Influencers in Data,” and he is an award-winning AI innovator.
Doug’s book, Infonomics: How to Monetize, Manage, and Measure Information for Competitive Advantage, was selected by CIO Magazine as the “Must-Read Book of the Year,” a “Top 5 Books for Business Leaders and Tech Innovators,” and by the Wall Street Journal as one of its “5 Summer Reads for CIOs.” His latest book, Data Juice: 101 Real-World Stories of How Organizations Are Squeezing Value From Available Data Assets has received accolades from business, data, analytics, and IT executives and practitioners around the world.
Previously Doug was a Distinguished Analyst with Gartner’s Chief Data Officer research and advisory team and was a three-time Gartner annual thought leadership award recipient.
In addition, he launched and managed the Deloitte Analytics Institute, is a Forbes contributing writer and has been published in the Wall Street Journal and the Financial Times among other journals. Doug has guest-lectured at major business schools around the world and is a visiting professor with the University of Illinois Gies College of Business where he teaches Infonomics and Business Analytics Executive Overview courses, which are also available online via Coursera. He also co-chairs the annual MIT Chief Data Officer Symposium, is on the faculty at Carnegie Mellon University’s Heinz College, is a member of the World Economic Forum’s data exchange initiative, a member of the American Economic Association, and sits on various advisory boards.
https://www.douglasblaney.com/about