

Why AI Agents Struggle with Complex Software Failures: A conversation with Greg Law
“Code generation has become cheap. Understanding software behavior hasn’t.”
— Greg Law, Founder and CEO, Undo
Q1. Your new research suggests that AI has made writing code easier, but 79% of engineering leaders say release cycles are no faster than before. Why hasn’t the productivity gain from code generation translated into faster software delivery?
Greg Law: Because writing code isn’t the whole job. AI has become extraordinarily good at producing code, but for mission-critical enterprise systems such as DBMSs, somebody still has to understand what that code does, determine whether it’s correct, and generally take ownership and accountability for it and be responsible when something goes wrong.
Modern coding agents are amazing but we’re a long way from being able to vibe code mission-critical infrastructure. AI can help with code review and understanding and debugging, but it’s not advanced at the same rate as it has for code generation, so the gap is widening and the bottleneck is becoming more and more extreme.
Our research found that engineers spend around 42% of their time debugging, compared with roughly a quarter actually producing code.
As an industry we’ve dramatically accelerated one part of the software development lifecycle without really addressing some of the much larger bottlenecks downstream. In some cases, we’ve made them worse.
Code generation has become cheap. Understanding software behavior hasn’t.
Q2. The report argues that writing code was never the main bottleneck in software engineering. Has the industry been measuring AI productivity in the wrong place?
Greg Law: I think so. Lines of code generated is attractive because it’s easy to measure. But nobody gets paid for producing lines of code. We get paid for delivering software that works. As Bill Gate said decades ago, we shouldn’t talk about lines of code produced, we should talk about lines of code spent!
The more interesting measures are things like: How long does it take to get a change into production? How many defects escape? How long does it take to understand an unexpected behavior? What’s the mean time to root cause when something fails?
If I generate a thousand lines in seconds but spend two days working out why the system is behaving incorrectly, I haven’t gained very much.
Q3. What changes when AI can generate code much faster than engineers can understand it? Are we creating a “comprehension gap” in software engineering?
Greg Law: Yes, and I think that’s one of the more important consequences of AI-assisted development that isn’t being discussed enough.
Historically, if you wrote the code yourself, you at least started with some mental model of what it was supposed to do. You might not understand every consequence of it, but there was a degree of inherent comprehension. There was intent.
With AI-generated code, that relationship changes. You can have perfectly plausible-looking code entering a system that nobody on the team really understands.
The survey found that engineering leaders estimate 35% of AI-generated code is not fully comprehended before it reaches production.
And the difficult failures aren’t normally caused by a line of code that is obviously nonsense. They’re caused by code that’s almost right.
Database systems are a good example. A change can be perfectly correct in most executions and fail only under a particular transaction ordering, thread interleaving or sequence of state changes. Those are exactly the failures that are hardest to reason about from source code alone, and hardest to diagnose when they strike in production.
Those are exactly the problems where looking at the source code isn’t enough. You need to understand what the software actually did.
So the risk is that AI increases the amount of software we’re producing much faster than it increases our ability to understand that software.
Q4. The report says 80% of engineering leaders believe coding agents struggle to solve difficult problems in large-scale, complex codebases. Why? Is this fundamentally a limitation of today’s models, or a limitation of the information we give them?
Greg Law: Increasingly, I think it’s an information problem. The obvious reaction when an agent fails is: we need a better model. But that’s only half the story.
Imagine asking a very experienced engineer to diagnose a concurrency failure in a storage engine. You give them the source, some logs and the documentation, but you don’t let them run the program or inspect what actually happened.
They might come up with a very plausible hypothesis. But that’s what it is — a hypothesis.
AI is in exactly the same position.
Source code tells you what a program could do. It doesn’t necessarily tell you what it did during a particular execution.
My view is that continually throwing a more powerful model at the problem misses something fundamental. If the input is incomplete, you’re asking the model to guess. Give the agent better evidence and suddenly even a less expensive model can become dramatically more capable.
Q5. You argue that agents need “runtime context.” Can you explain precisely what runtime context is, and how it differs from adding more logs, traces or other conventional diagnostic information?
Greg Law: Logs and traces are examples of runtime context. And agents are great at ingesting this runtime context and combining with the source code. But it’s exactly the same problem as human engineers have when looking at logs and traces – they’re incomplete. If you get lucky the information you need is in there. All too often, it’s not; the critical piece of info about what the system did in the lead-up to the error is just not there.
For years Undo has provided human engineers with complete program recording of program execution, effectively 100% of the runtime context. We need to bring that to the agents too.
Not just a handful of log lines or a stack trace when it crashes. Capture the execution so that afterwards you can ask: Where did this value come from? Which thread wrote it? What sequence of events led us here?
That’s the complete runtime context.
Logs are useful, but they’re selective. Somebody has to decide beforehand what to log. When the bug depends on something you didn’t log, you have to add instrumentation and reproduce it again. In many cases, if you knew to log it ahead of time you probably wouldn’t have made the mistake in the first place! (Where ‘you’ here can be a human or an AI.)
A recording changes that. Undo creates a deterministic, self-contained recording of execution that can be interrogated afterwards.
For an AI agent, that is enormously powerful because it can move beyond reading descriptions of the software and start reasoning about software behavior.
Static context helps an agent understand what the code says. Runtime context helps it understand what the code did.
Q6. How do you establish that an AI-generated root-cause analysis is correct? In mission-critical software, is producing an answer enough, or must the agent also be able to provide evidence that engineers can independently verify?
Greg Law: Producing an answer isn’t enough. Models are very good at producing explanations that sound plausible, but plausible and correct are two different things.
If an AI tells me, “this looks like a race condition,” my next question is: Show me. Which threads were involved? What was the ordering of events? Where did the incorrect value come from?
The interesting thing about recording execution is that the agent doesn’t just have more information with which to form a hypothesis. It also has evidence against which that hypothesis can be tested.
That changes the nature of the interaction. You can move from “I think this may be the cause” to “This value became incorrect at this point in execution; it was written here, by this thread, as a consequence of this earlier event.“
This is especially important with today’s AIs which suffer from being confidently wrong. It might give a confidently correct answer 4 times out of 5, but that fifth time where it goes down the rabbit hole due to being confidently wrong can be very expensive: a lot of time (and tokens!) are spent going down a blind alley, and eventually the agent just gives up and tells the human to fix it themself, often steering the human in the wrong direction first!
For mission-critical software like databases, networking systems, large-scale simulations, that distinction between assertion and evidence is going to become increasingly important.
Q7. Your research report suggests that better context may allow less expensive models to solve problems that would otherwise require frontier models. Is the next major AI optimization problem therefore not simply “which model should I use?”, but “what information should I give the model?”
Greg Law: Very much so. There’s been an enormous amount of focus on model selection, but model intelligence is only one variable. The other variable is context.
A very capable model with poor context will perform worse than a less capable model with exactly the evidence it needs.
Complex debugging tasks can be extraordinarily token-intensive if the agent is repeatedly reading huge codebases, generating hypotheses and starting again, especially when it gets into the add logs, rebuild and rerun loop. Give it a recording of the relevant execution and you radically reduce the search space.
Nearly two-thirds of the engineering leaders we surveyed said that the cost of higher-tier models was prohibitive for this kind of work.
So I think the next stage of enterprise AI isn’t simply going to be about buying access to a smarter model. It’s going to be about giving models better inputs.
In software engineering, runtime behavior is one of the most valuable inputs we’ve historically been missing.
In fact, our CTO recently presented data showing a cheaper model with runtime context outperforming a more expensive model working from logs. (ref. CppCon 2026 conference poster). This demonstrates clearly and quantitatively how rich runtime context makes AI smarter, faster and cheaper.
Q8. Looking three to five years ahead, do you expect engineers to spend less time debugging themselves and more time supervising autonomous investigations? If so, how does the role of the software engineer change?
Greg Law: It’s already happening. Many of our customers today have fully automated CI pipelines that go through triage, root-cause analysis, fix. Recordings are a key part of this to get the confidence that the diagnosis is correct and the fix works as expected. If we’re to realise the productivity promises of AI, it’s the only way: we need to apply AI to the whole SDLC.
When a test fails or there’s a production issue, an agent should be able to capture the failure, interrogate the execution, trace causality and present the engineer with the root cause and the evidence behind it, and then ideally suggest the fix. Some of our customers are already automating root-cause analysis in CI and, in some cases, production.
That doesn’t remove the engineer. It changes where they spend their time: less on collecting evidence and reconstructing what happened, more on deciding the right architecture and broader engineering judgments.
For me, that’s a far more interesting application of AI in software engineering than simply generating more code.
Q9. Your research breaks out findings by industry and suggests that data management teams are particularly concerned about the volume of AI-generated code entering complex codebases: 60% say engineers struggle to review it effectively and end up merging too many AI-generated errors, compared with 46% across industries overall. Why do you think this challenge is especially pronounced in database and data-management software?
Greg Law: I think databases are a particularly unforgiving environment for this because correctness is so dependent on behavior over time. It isn’t enough for a function to look locally correct. You have concurrency, state transitions, recovery paths, memory behavior and interactions between subsystems, often over very long-running executions. A bit of state gets corrupted and everything carries on working just fine for some time until eventually the system falls over. And these things are deployed at such a scale that if something will go wrong one time in a billion then it’s going to happen all the time!
So AI-generated code can look entirely plausible in review and still introduce a failure that only appears under a particular runtime condition. That makes “just review the generated code more carefully” a pretty weak scaling strategy.
Increasingly, the important question is not “Does this code look right?” but “What did this change actually cause the system to do?” And source code alone often can’t answer it, neither for a human nor for an AI.
Q10. The report finds that 82% of engineering leaders are concerned that the token costs of coding agents will rise sharply as Anthropic and OpenAI prioritize IPO economics. If runtime context lets cheaper models match frontier models on debugging tasks, does that weaken the case for always using the most powerful model and change how engineering teams think about model selection?
Greg Law: I think it changes the economics quite fundamentally, because a bigger model isn’t always the answer. If you’re asking it to debug from incomplete evidence, you may just be paying more for a better guess. And it’s not just about cheaper models – if the AI gets the right answer first time, rather than repeated guesses and adding logging and rerunning, then it’s going to get to the conclusion using far fewer tokens.
Nearly two-thirds of the engineering leaders we surveyed said the cost of higher-tier models is already prohibitive for comprehension and debugging.
So the question becomes less “What’s the best model?” and more “What’s the least expensive model that can solve this reliably with the right context?”
Resources
Research report: Overcoming the limitations of coding agents in complex software systems
Agentic Debugging Live – Without a Safety Net, GenAI-X
…………………………………………………………
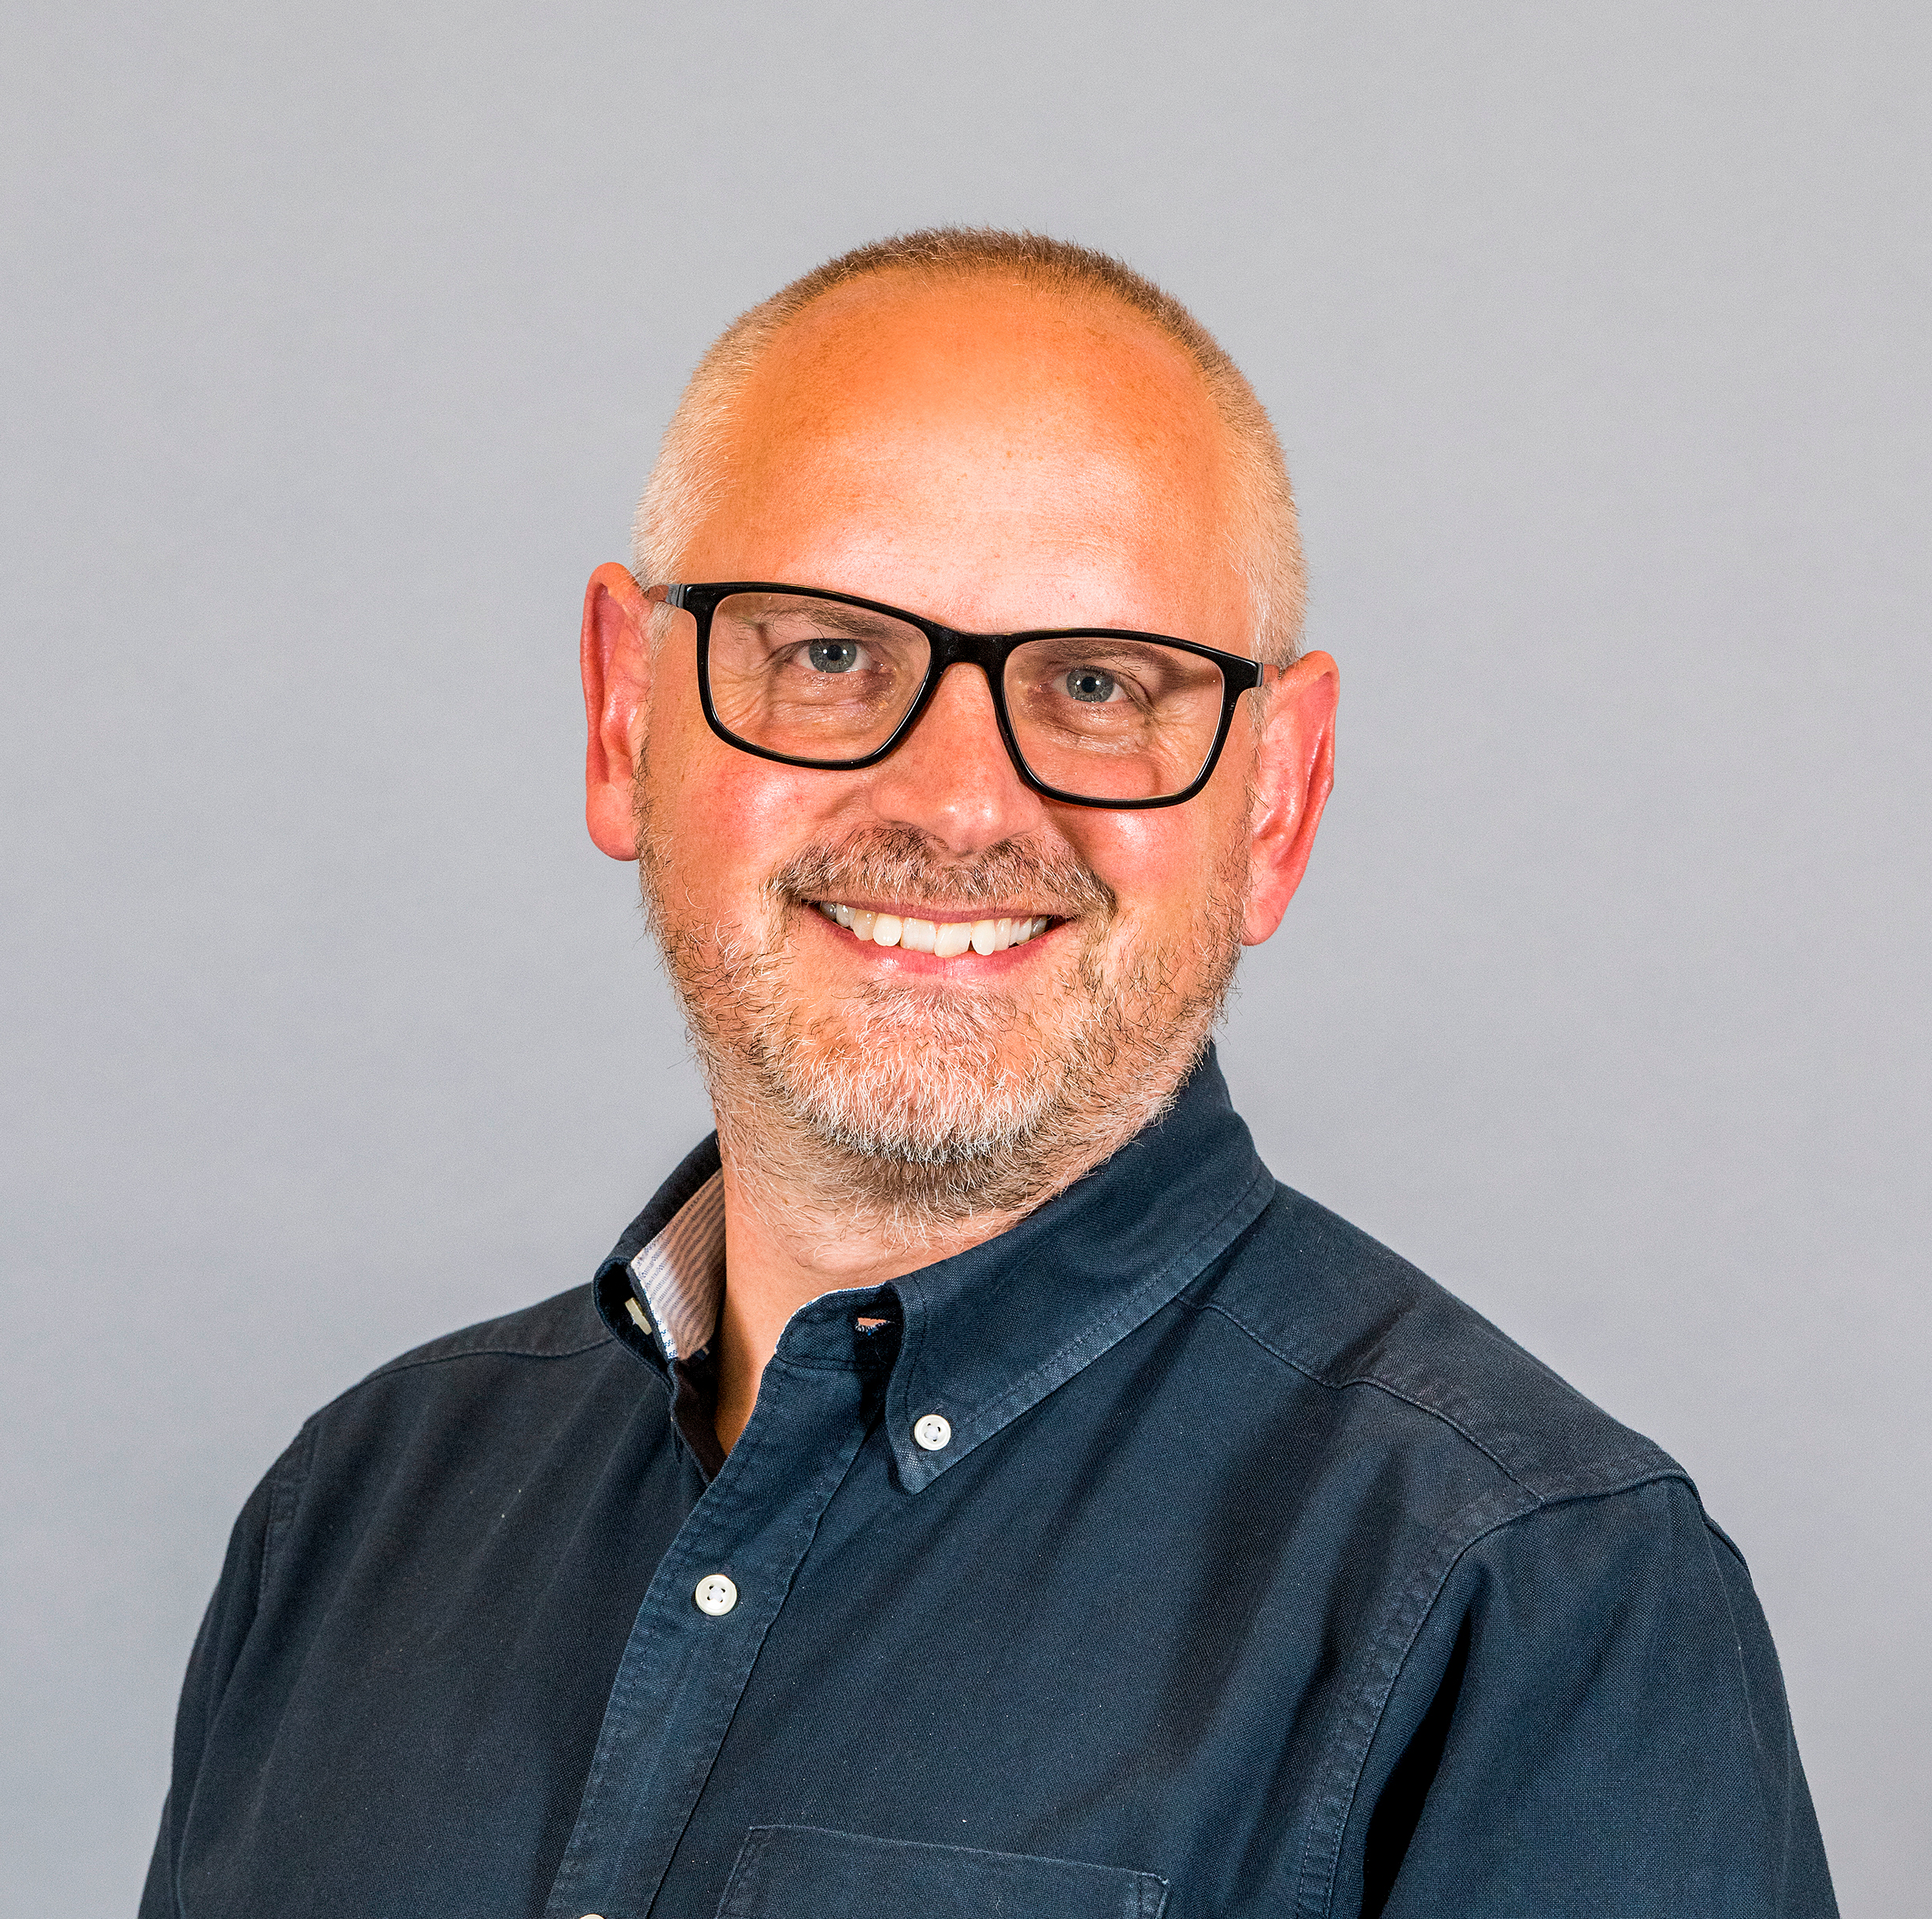
Greg Law is the founder and CEO of Undo. A systems engineer at heart, he has spent more than 25 years building and leading software teams working on complex, high-performance codebases where failures are costly and debugging is a bottleneck. His career spans Acorn, startups including NexWave and Solarflare, and ultimately the creation of Undo.
Undo’s core technology grew from Greg’s firsthand frustration with traditional debugging. While at Acorn, he and co-founder Julian began developing a different approach: recording real program execution so difficult bugs could be diagnosed deterministically rather than guessed at.
As CEO, Greg has taken Undo from an early technical breakthrough to an enterprise platform used by engineering teams that cannot afford broken releases, prolonged outages, or unresolved defects. He is also a regular conference speaker on software engineering, debugging, and the challenges of building reliable complex systems.
Greg holds a PhD from City University, London, and lives in Cambridge with his family. These days, his coding mostly happens on long flights. In his spare time, Greg catches up on emails.

Comments are closed.